Cost Attribution
Which Teams Are Overspending on Anthropic When OpenAI Would Cost Less for the Same Task
Task-level routing sends cheap work to budget models and reserves flagship tiers for reasoning.
Marcus Oduya
· 8 min read
Task-level routing sends cheap work to budget models and reserves flagship tiers for reasoning.
Consistent metadata at the gateway enables real-time cost attribution across teams and projects.
Gateway attribution tags let finance track AI spending by team before costs hit budgets.
Route LLM requests through a proxy to track spend by team and model in real time.
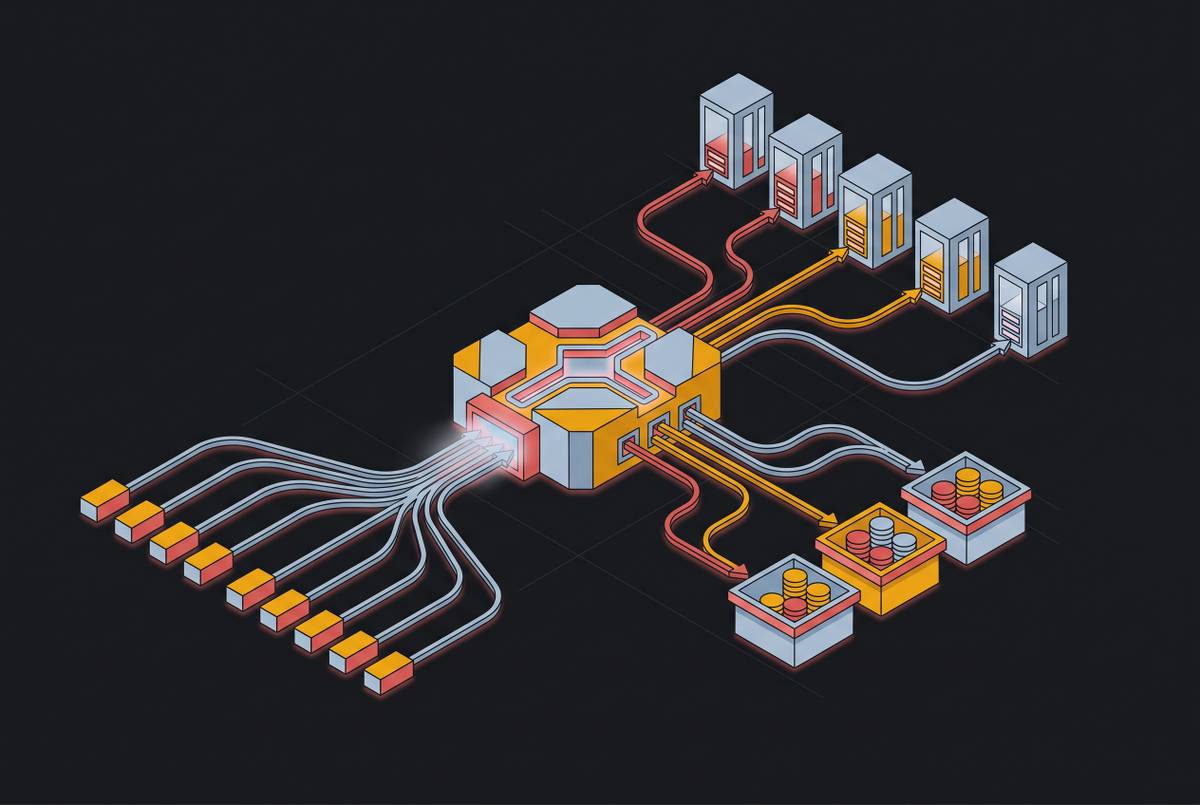
A gateway layer attributes each LLM request to its owner before billing.
Gateway-layer enforcement catches expensive requests before they reach your provider.
Fallback routing at the infrastructure layer protects against provider outages and runaway costs.
Tight schemas cut bloat from AI responses and let cheaper models handle extraction work.
Different providers' cache mechanics create vastly different real costs.
Real cost attribution requires four dimensions tracked per-request in real time.
Splitting tasks across models by complexity cuts AI costs by up to 72 percent.
Standard logs miss the moments that matter most in LLM audits.